After this assignment, you will be able to:
- design an AST for a small language and build it in an LL(1) parser’s actions, with evaluation as a separate pattern-matching traversal.
- compare ASTs, control flow graphs, and three-address code as program representations.
- translate an AST into a target representation by recursive traversal – here, compiling regular expressions to an NFA via Thompson’s construction.
Overview
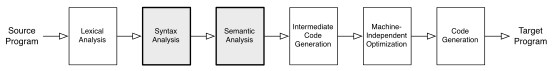
This week’s goal is to explore the internal data structures used by a compiler to organize and manipulate a source program. These data structures are the core of a compiler, and developing a good set of programming abstractions is essential for managing implementation complexity.
There are several specific topics for the week:
Building abstract syntax trees (ASTs) during parsing, and examining other intermediate representations.
Developing a general structure for symbols information.
Readings
The readings are from a variety of sources, listed roughly in the order in which they will be most useful. Some parts are pretty light and fill in background material; others are more directly related to the problems below.
- Engineering a Compiler,
Cooper and Torczon, 4.1-4.3, 5.1-5.4, 5.7.
Chs. 4.1-4.3 are mostly background material — skim for the basic ideas; 5.1-5.4 cover intermediate representations and ASTs; 5.7 covers scoping and symbol tables. - Modern Compiler Implementation
in Java, Appel, Ch. 4.
Skim. If you have seen the Visitor design pattern, compare what Appel describes about AST visitors to the operations our case-class trees support.
Exercises
This question requires some programming. You may work with a partner if you wish. The problem explores how parsers construct values — and, in particular, abstract syntax trees — as they go. In scup every rule produces a value:
%type expr: Intsays ruleexprmatches tokens and its blocks build anInt. Until now our calculator evaluated on the fly:%left "+" "-" expr ::= %binary(term) { if $2.text == "+" then $1 + $3 else $1 - $3 } ;Modern compilers do essentially no real work during parsing. Instead, the parser builds an abstract syntax tree, and all subsequent analysis is performed by separate passes over the tree. For the calculator, that means AST classes like:
  abstract class Expr
  case class Add(left: Expr, right: Expr) extends Expr
  case class Number(value: Int) extends Expr
and a grammar of
%type expr: Exprwhose operator blocks produce tree constructors instead of arithmetic:expr ::= %binary(term) { if $2.text == "+" then Add($1, $3) else Sub($1, $3) } ;Starting from your Calculator from Lab 2:
Define AST case classes for the calculator language and change the grammar’s
%types toExpr, so that parsing builds a tree and performs no arithmetic. Then add a separateevalExpr(e: Expr): Intfunction toCalc.scalaas a pattern-matching tree traversal (see pattern matching on case classes in the Scala tour), and changeeval(source)to parse the source to anExprand evaluate it with that function.Your Lab 2 calculator already parses comma-separated programs with
program ::= %list(expr, ","). Changeprogram’s%typetoList[Expr], so that “4,1+7” parses to a list of trees. (Tip: passtrace = truetoparseAsto watch the parser work through an input and check that it matches your intuition.)Update
evalListinCalc.scalato parse a program to aList[Expr]and evaluate each tree withevalExpr, and check that all your Lab 2 tests still pass.
No need to bring this code to our meetings, but be prepared to talk about the above items.
[Adapted from Cooper and Torczon]
Show how the code fragment
  if (c[i] != 0) {
    a[i] = b[i] / c[i];
  } else {
    a[i] = b[i];
  }
  println(a[i]);
might be represented in an abstract syntax tree, in a control flow graph, and in quadruples (or three-address code — see the simple TAC definition).
Discuss the advantages of each representation.
For what applications would one representation be preferable to the others?
This question also involves programming. It is more substantial than most of the homework questions, so please don’t wait until the last minute. You may work with a partner if you like. The following grammar describes the language of regular expressions, with several unusual characteristics described below:
\[\begin{array}{rcl} R & \rightarrow & R ~ \tm{|} ~ R \\ & | & R ~ \tm{.} ~ R \\ & | & R ~ \tm{*} \\ & | & R ~ \tm{?} \\ & | & R ~ \tm{+} \\ & | & \tm{(} ~ R ~ \tm{)} \\ & | & \nt{letter} \\ & | & \tm{[} ~ L ~ \tm{]} \\ & | & \tm{let} ~ \nt{id} ~ \tm{=} ~ R ~ \tm{in} ~ R \\ & | & \nt{id} \\ & | & \tm{@} \\[1ex] L & \rightarrow & L ~ \nt{letter} \\ & | & \nt{letter} \end{array}\]
The
*,?, and+operators have higher precedence than concatenation (.); and, in turn, concatenation has higher precedence than alternation. A letter can be any lower-case letter ina–z, and@stands for \(\epsilon\). The term[\(L\)]indicates an alternation between all of the letters in the letter list \(L\). Here are some examples:a.b+:afollowed by one or moreb’s.[abc]: any ofa,b, orca.(b|c)*:afollowed by any number ofb’s andc’s.a|@: eitheraor \(\epsilon\), which is represented by@.
In order to describe more interesting patterns succinctly, our language has “let”-bindings for id’s (which are identifiers starting with capital letters), as in the following:
let C = (c.o.w)* in
  C.m.C.m.C
which is the same as
(c.o.w)*.m.(c.o.w)*.m.(c.o.w)*. Bindings can be nested, and one binding can redefine an already bound name:let C = c.o.w in C.C. let C = m.o.o in C*which is equivalent to
c.o.w.c.o.w.(m.o.o)*.The starter code for this problem includes a complete lexer (
re.lex.RELexer) and a skeletalscupgrammar (re.parser.REParser) for regular expressions. You are to complete the parser, design an AST package for regular expressions, and then write code to translate regular expressions into NFA descriptions that can be executed on the NFA simulator included in the starter (packagenfa). The simulator uses the same set-of-states algorithm you wrote in Lab 1, but its.nfafile format is different (edges are labeled with any ofa–z) — don’t confuse the two.To begin, accept the GitHub invitation email to your team’s HW 4 “RECompiler” repository and clone it. It is set up like the project for the first question and PA 2. You are free to again work with a partner or two on this question.
The
mainmethod inre.Maincurrently reads a regular expression from its first argument. It is executed from the command line as follows:sbt "run ex1.re"Before you can successfully parse expressions, however, you must complete the grammar in
re.scup. Structure it with one rule per precedence level, as you did for a simpler version of this language in HW 3.Design a hierarchy of case classes to represent regular expression ASTs. The root of your hierarchy should be the
re.ast.RENodeclass that I have provided. Your hierarchy should contain a reasonable, minimal collection of classes. Not every concrete syntactic form needs to have an analog in the abstract syntax (eg, “[L]” can be expressed as an alternation, etc.).Extend the parser to generate an AST for the parsed regular expression.
Your AST classes should use Scala collections —
List,Option, and friends — to store their data. Options are useful for storing “optional” values; I encourage you to use them where appropriate.For
let-bindings, remember that grammar rules are static, so you cannot thread an environment through the parse. Instead, have your blocks build a small intermediate tree of your own that still containslets and names, and then substitute definitions for names in a second “resolve” pass inre.parser.REParser, so bindings never show up in your final AST (see the notes at the top ofre.scup). The resolve pass maintains a map from id’s to their definitions and should throw are.error.REErrorif it encounters an id that has not been defined.You may use either static or dynamic scoping for names. The two differ only when a definition mentions another name that is later rebound. Consider:
let A = a in
  let B = A in
    (let A = c in
      B
    ).B
Static scoping: a name inside a definition means the binding in scope where the definition is written. When
Bis defined,Ameansa, soBmeansaeverywhere, and the whole expression isa.a. To implement this, resolve each definition before adding it to the map.Dynamic scoping: a name inside a definition means the binding in scope where the definition is used. The first use of
Boccurs insidelet A = c, so thereBmeansc; the second use ofBoccurs outside it, whereBmeansa. The whole expression isc.a. To implement this, store each definition in the map unresolved, and resolve it when you substitute it for a name.
Either choice is fine; the provided tests do not distinguish them. You may assume that definitions are never circular (for example,
let X = X.a in Xwill not appear), so the dynamic approach always terminates.Complete the
re.PrettyPrintclass for generating printable, fully parenthesized forms of expressions represented by aRENode(for example,a.b*prints as(a.(b*))), and extend themainmethod to print the parsed expression.Write a
re.NFABuilderclass to build aNFAfor a regular expression represented by aRENode. I have provided there.NFAclass to help in this step — your builder simply needs to create a newNFAobject and invoke the appropriate methods on it to create states and edges. See the classes documentation for details on theNFAclass. This process will be a recursive traversal of the AST. Think carefully about what information would be most useful to propagate down the tree and back up during the traversal.Use the
NFA.toString()to write the resulting NFA to a file. Specifically, whenre.Mainis run on an input filex.re, it must write exactly one file namedx.nfa(that is, the input’s base name with a.nfaextension) into the current directory — the provided tests require this. The starter’sMain.writeNfaFilehelper handles that naming; just call it with your NFA. So, running onex1.reproducesex1.nfa, which can then be run with the NFA simulator:sbt "runMain nfa.NFASimulator ex1.nfa ab cow"The alphabet for this simulator is
a–z, plus@for \(\epsilon\).
If
ex1.recontains the expression “a.(b|c)*”, your program should generate an NFA similar to the following:7 6 0 a:(1) ; 1 @:(2,3,6) ; 2 b:(4) ; 3 c:(5) ; 4 @:(6) ; 5 @:(6) ; 6 @:(1) ;Running
sbt "runMain nfa.NFASimulator ex1.nfa ab cow abccccc a"will then result in
ab: yes
cow: no
abccccc: yes
a: yes
sbt testruns the full pipeline the same way: for eachtests/X.re,re.PipelineTestsrunsre.Mainto produceX.nfaand checks the simulator’s answers againsttests/X.re.expected. Be sure to test your program on more sophisticated examples, too — add your own.re/.re.expectedpairs totests/.To help you debug the last two steps, the
NFAclass also contains aprintDot()method that generates the file “nfa.dot”. This graphical representation of the NFA can be viewed by issuing the following command from the command line to generate a PDF file:dot -Tpdf < nfa.dot > nfa.pdfThe
dotcommand is part of Graphviz. To install it on your laptop, usebrew install graphvizon a Mac orsudo apt install graphvizon Ubuntu/WSL.Please come to your meetings with your final code committed to your GitHub repository. Time permitting, I’d like to do mini-code reviews of your solutions.